As enterprise AI deployments mature, a key design decision is how a language model accesses information beyond its training data. Retrieval-Augmented Generation (RAG) and Agentic RAG offer two distinct approaches to this challenge.
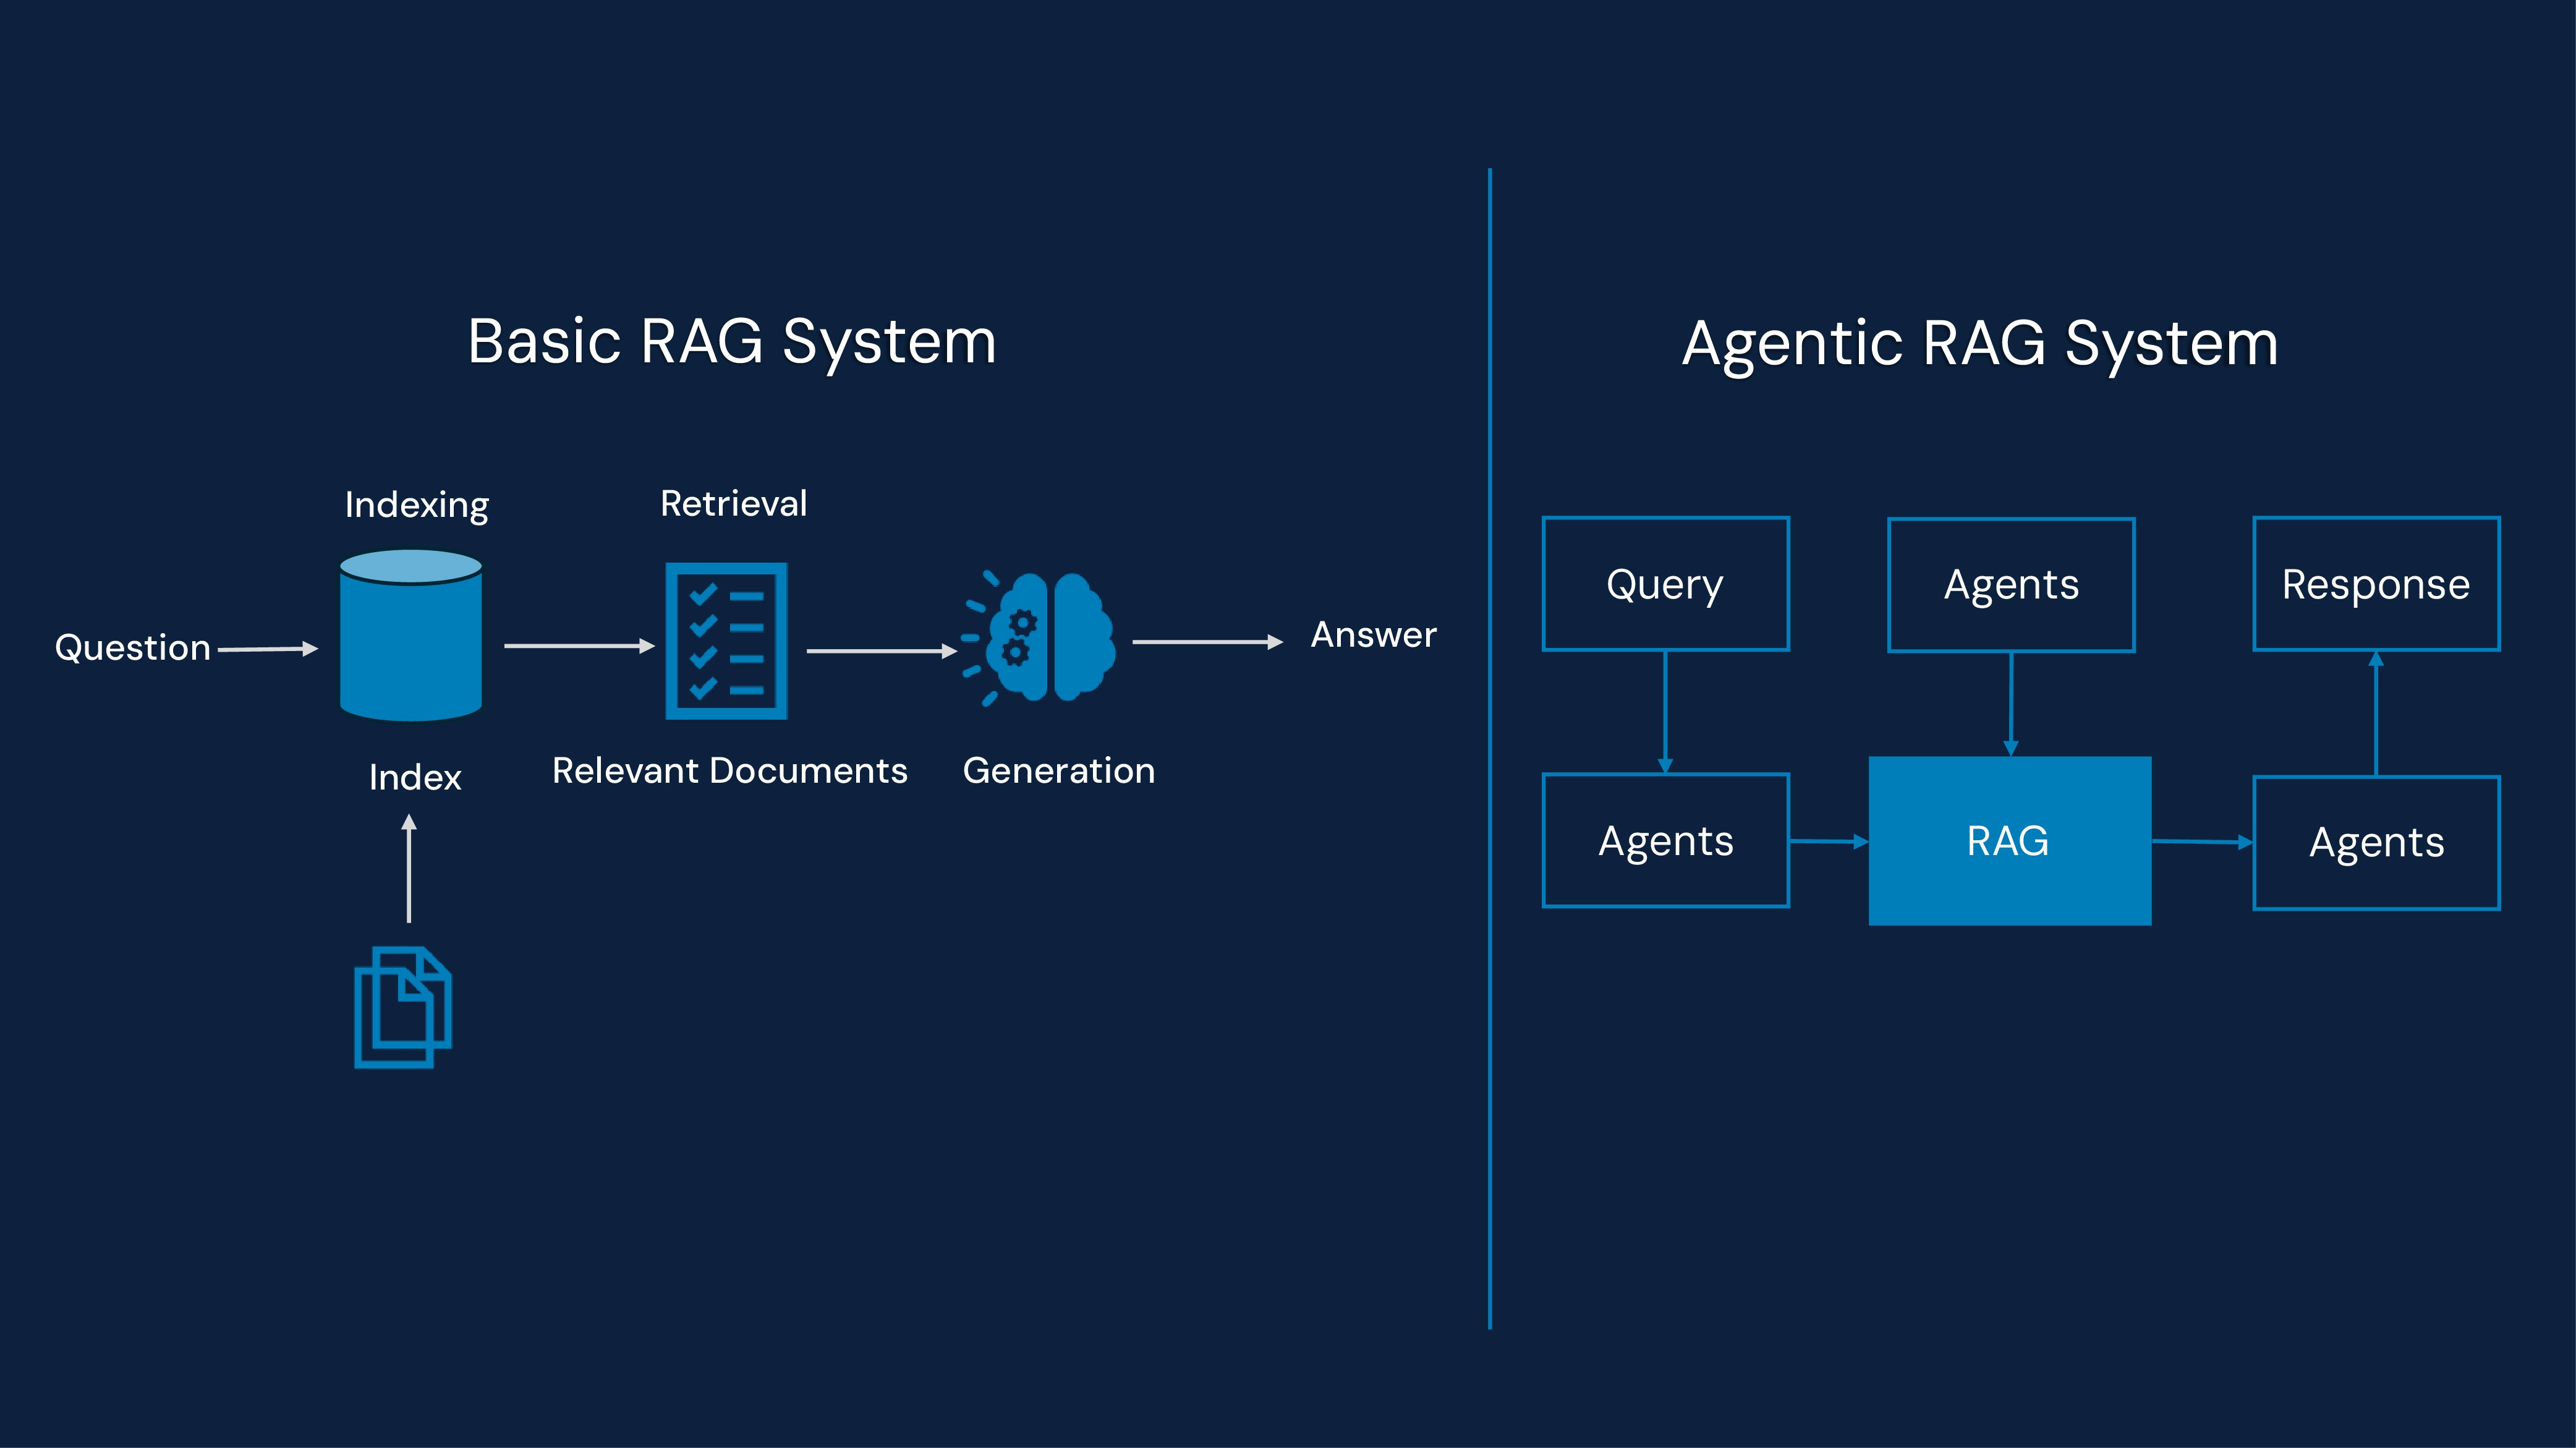
RAG integrates a language model with a retrieval layer that gathers information from external sources. Rather than relying solely on trained knowledge, the system fetches relevant content from databases, APIs, or knowledge repositories and supplies this context to the model before generating a response.
This architecture is widely used to ground LLMs, improving factual reliability and reducing hallucinations in domain-specific applications.
Key components of RAG
Retrieval Mechanism: Searches external knowledge sources for relevant information.
Language Model (LLM): Uses retrieved information to generate responses that are grounded in the available context.
Fusion Layer: Integrates retrieved information into the generated response to enhance LLM accuracy.
How does RAG work?
When a user submits a query, the retrieval layer searches external knowledge sources for relevant information. This information is then provided to the language model as supplementary context before generating a response. The final answer incorporates both retrieved content and the model's built-in knowledge.
Benefits of RAG
Improved factual correctness compared to standalone LLMs.
Access to real-time data for more up-to-date responses.
Reduced hallucination risk by grounding responses in external knowledge.
Enables organizations to provide approved knowledge sources to AI systems without retraining the model whenever information changes
Limitations of RAG
The retrieval layer may return irrelevant, incomplete, or duplicate content, which can reduce response quality.
It does not adapt its search strategy when new context emerges.
Retrieved content is provided to the model without further validation.
RAG is less effective for tasks that require planning, iteration, or multi-step reasoning.
Choosing the right retrieval framework for your AI
Aspect | RAG | Agentic AI |
|---|---|---|
Static, single-pass retrieval using predefined queries. | Multi-step retrieval with the ability to revise and refine searches as new information becomes available. | |
Query optimization | No real-time refinement; limited handling of ambiguity. | Refines queries when gaps in information or intent are identified. |
Information verification | No verification: retrieved data fed directly into LLM. | Can compare and validate information across multiple sources before responding. |
Self-learning and adaptability | No learning from the user | Can adapt based on feedback via reinforcement learning (RLHF). |
Response accuracy and context | May lack nuance or depth due to static retrieval. | Evaluates additional context before responding and can ignore information that is not relevant to the task. |
Computational cost and latency | Fast and lightweight; optimized for speed. | Requires more computation and typically introduces additional latency, but can handle more complex workflows. |
Use case suitability | Best for basic tasks like customer support and general-purpose assistants. | Well-suited for high-stakes environments like legal, financial, medical, and enterprise AI, requiring advanced AI workflow automation. |
RAG vs. Agentic RAG: Top use cases
Industry | RAG (Retrieval- Augmented Generation) | Agentic RAG |
|---|---|---|
Customer support | Enhances chatbots with accurate, document-grounded responses from FAQs, manuals, and help centers. | Uses user history, conversation context, and multi-step reasoning to address more complex issues. |
Healthcare | Summarizes medical literature and retrieves clinical guidelines for faster decision support. | Combines patient records, research, and treatment information while applying adaptive reasoning. |
Finance and compliance | Retrieves policy documents and regulatory updates for quick reference. | Performs multi-step analysis, identifies anomalies, and evaluates compliance requirements. |
Enterprise knowledge | Pulls internal documentation from SharePoint, Notion, or Slack to answer employee queries. | Retrieves, validates, and summarizes internal information while accounting for context. |
Education | Delivers personalized answers from course materials and academic databases. | Creates adaptive learning paths, refines information requests, and generates tailored study plans. |
Answers product-related questions using inventory, order history, and support docs. | Handles more complex workflows such as issue diagnosis, returns, and record updates. | |
Scientific research | Retrieves relevant papers and data for literature reviews. | Plans multi-hop research tasks, compares findings, and produces structured summaries. |
Business intelligence | Generates reports from structured data and dashboards. | Automates KPI analysis, trend identification, and decision-support workflows using external tools and reasoning agents. |
Conclusion
The distinction between RAG and agentic AI concerns suitability rather than replacement.
For applications requiring accurate, source-grounded answers, RAG is often sufficient. When planning, validation, or coordination across multiple steps is needed, agentic AI offers greater value.
Many enterprise systems will ultimately combine both approaches, using retrieval to ground responses and agentic capabilities to manage complex tasks.